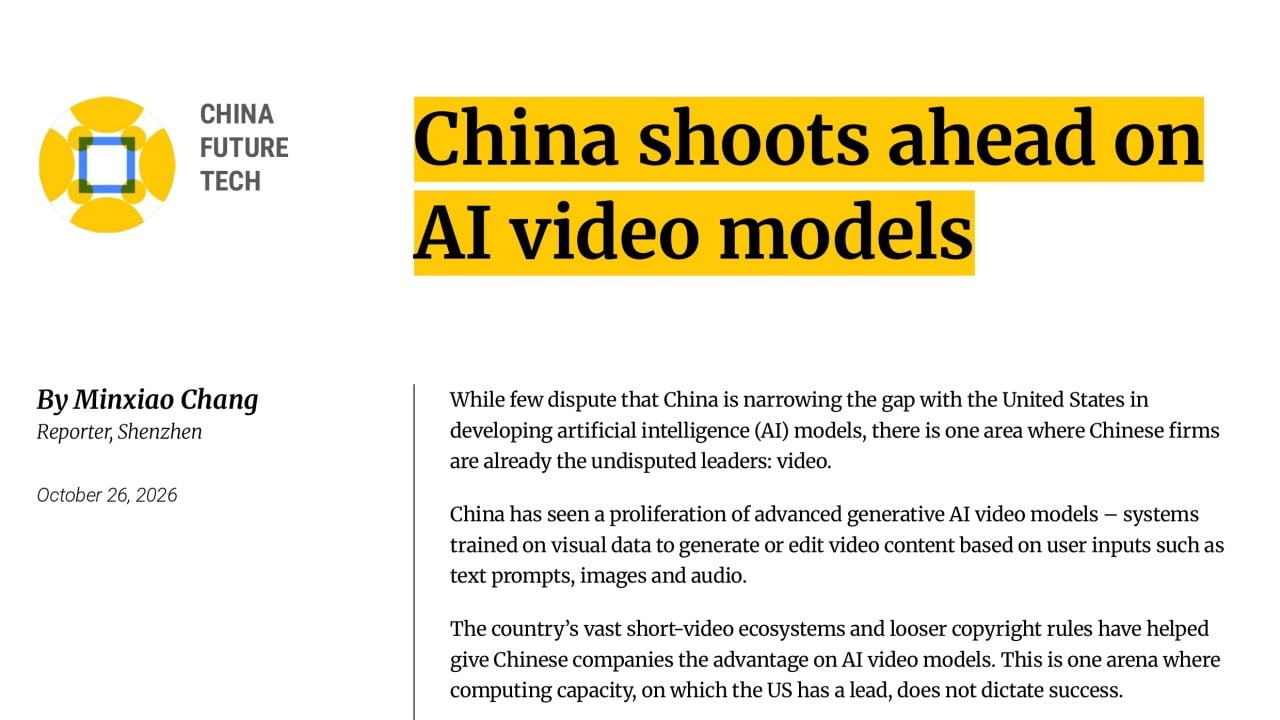
China has overtaken Silicon Valley in commercial AI video generation not through a single breakthrough, but by shipping usable, high-definition tools directly to the public while American labs remained trapped in safety reviews and limited demos. Models like Kuaishou’s Kling, Shengshu’s Vidu, and ByteDance’s Jimeng bypassed the gated waitlist model favored by Western rivals. By pairing aggressive open-access rollouts with massive domestic short-form video datasets, Chinese tech firms turned generative video from a research novelty into an everyday production utility.
Silicon Valley blinked. For months after OpenAI unveiled Sora in February 2024, the industry operated under the assumption that American labs held an insurmountable lead in temporal consistency and physics simulation. Yet while Sora sat behind closed doors for red-teaming and Hollywood courtships, Chinese engineering teams dismantled the architecture, replicated the core Diffusion Transformer mechanics, and put working products into the hands of millions of creators. For another look, consider: this related article.
The Architecture Behind the Surge
Understanding this shift requires looking under the hood of modern video synthesis. Early AI video tools relied on U-Net architectures that stitched frames together like a flipbook, resulting in warping objects and flickering textures. The breakthrough came with the Diffusion Transformer (DiT), which treats video not as a sequence of flat images, but as a unified grid of spatiotemporal patches.
Chinese researchers did not invent the DiT framework, nor did they pioneer the underlying 3D Variational Autoencoders (VAEs) that compress raw pixel data into manageable latent spaces. What they mastered was execution at scale. Kuaishou’s Kling AI demonstrated native 1080p output at 30 frames per second, capable of generating two-minute continuous clips with coherent object permanence. When a character turns their head or pours water from a glass, the model maintains basic physical logic rather than dissolving into surrealist soup. Similar reporting on the subject has been provided by Wired.
MiniMax followed with Hailuo AI, showcasing fluid camera tracking and remarkably expressive human micro-expressions. ByteDance, leveraging decades of expertise in visual recommendation algorithms, deployed Seaweed and PixelDance, focusing heavily on complex motion dynamics and multi-subject interactions. Meanwhile, Zhipu AI introduced CogVideoX, releasing open-weight versions that allowed independent developers to fine-tune video models on consumer-grade hardware.
Why Compute Sanctions Failed to Stop Video Progress
Western analysts assumed American export controls on advanced Nvidia GPUs—specifically the H100 and A100 chips—would starve Chinese labs of the raw compute required for heavy multimodal training. That assumption proved flawed for two distinct reasons.
First, major Chinese tech conglomerates stockpiled tens of thousands of high-end processors before the strictest export restrictions took effect. Second, and more importantly, chip scarcity forced an obsession with algorithmic efficiency. Unable to simply throw infinite compute at brute-force scaling, Chinese engineers optimized attention mechanisms, refined data-filtering pipelines, and improved compression ratios within their VAEs. Doing more with less hardware became a survival skill, resulting in leaner inference costs that allowed companies to offer free daily credits to users worldwide.
The Data Advantage Nobody Talks About
Compute is only half the equation. Training a video model to understand how fabric folds, how light refracts through water, or how a crowd moves requires billions of high-resolution video clips paired with dense, accurate text descriptions.
Here, China possesses a structural advantage that Western startups struggle to match. Companies like ByteDance (owner of Douyin and TikTok) and Kuaishou sit atop the largest repositories of user-generated video on the planet. While Western labs face relentless copyright lawsuits from Hollywood studios, stock footage agencies, and news publishers over training data, Chinese platforms operate within an ecosystem where massive video libraries are already native to their business models.
The Captioning Bottleneck
Raw video is useless for training unless the model knows what is happening inside the frame. If a training clip is labeled simply as "dog running," the resulting AI will struggle to follow complex prompts involving camera angles, lighting moods, or specific actions.
Chinese labs invested heavily in automated dense video captioning. Using specialized vision-language models, they systematically re-annotated millions of hours of footage, generating paragraph-long descriptions for every few seconds of video. A clip isn't just tagged; it is dissected into foreground action, background movement, lens focal length, and color grading. When a user types a detailed prompt into Kling or Hailuo, the model responds with uncanny precision because its training data spoke that exact descriptive language.
Shipping Over Gatekeeping
The cultural divide between Beijing and San Francisco has never been clearer than in their respective go-to-market strategies. American AI labs operate under intense regulatory scrutiny, reputational anxiety, and fear of copyright litigation. Consequently, companies like OpenAI and Google adopted a defensive posture—releasing curated highlight reels, restricting access to vetted filmmakers, and delaying public launches while debating watermark standards and deepfake guardrails.
Chinese firms took the opposite route. They treated AI video as a consumer internet race, prioritizing rapid iteration over controlled perfection.
- Immediate Public Access: Within weeks of announcing their models, Kuaishou and MiniMax opened web interfaces to anyone with an email address or phone number.
- Real-Time RLHF: By letting millions of users generate millions of clips daily, these companies gathered massive amounts of Reinforcement Learning from Human Feedback (RLHF). Every time a user regenerated a prompt or downloaded a specific clip, the system learned which motion trajectories looked natural and which failed.
- Commercial Integration: Rather than treating video generation as a standalone novelty, platforms baked it directly into existing creator workflows, e-commerce ad generators, and mobile editing apps.
American startups like Runway and Pika Labs fought admirably to keep pace, pushing out Gen-3 Alpha and Pika 1.5 with strong stylized controls. Yet they found themselves competing against tech giants with deep pockets, massive domestic user bases, and zero hesitation about shipping fast.
The Illusion of Perfection
To read social media hype, one might think traditional filmmaking is already obsolete. It isn't. Despite impressive leaps, Chinese AI video models still suffer from fundamental limitations that restrict their use in high-end commercial production.
Temporal coherence breaks down quickly when prompts demand complex interactions between multiple hands, fast-paced martial arts, or strict adherence to real-world physics over extended durations. Text rendering inside video frames remains erratic. Characters still occasionally morph subtly when moving from shadow into bright light, and fine-grained directorial control—such as keeping the exact same actor across twenty different camera setups without facial drift—requires tedious workarounds using third-party image-to-video pipelines.
Furthermore, strict domestic content moderation governs every Chinese model. Prompts touching on sensitive political figures, historical events, or certain cultural themes are instantly blocked at the text-encoder level. For global brands or independent creators working on edgy narrative projects, relying exclusively on servers subject to Beijing's regulatory framework introduces obvious operational risks.
The Open-Source Wildcard
The most consequential development isn't the closed web apps—it is the open-weight releases. When Zhipu AI released CogVideoX and Alibaba followed with open video architectures, they handed the global developer community the keys to run generative video locally.
Consider a hypothetical mid-sized European advertising agency that cannot send unreleased client product footage to external cloud servers due to strict non-disclosure agreements. By downloading an open-weight Chinese video model and running it on local workstation clusters, that agency bypasses cloud privacy risks, avoids recurring subscription fees, and custom-trains the weights on its own brand assets. Open weights erode the moat of proprietary Western APIs faster than any marketing campaign ever could.
What Actually Matters in the Video Race
The narrative framing AI development as a simple two-horse race misses the deeper economic reality. Generating a ten-second clip of an astronaut riding a horse on Mars is a parlor trick; integrating controllable video synthesis into real-world production pipelines is a multi-billion-dollar industry.
Right now, the battleground has shifted from raw resolution to controllability. Creators do not want a slot machine that spits out random pretty footage after fifty tries. They want camera path trajectories, motion brushes that animate specific pixels while freezing others, lip-syncing that matches multi-language audio tracks, and consistent character sheets.
Chinese teams are moving aggressively into these exact granular controls. By pairing image-to-video workflows with precise kinematic parameters, tools like Kling and Vidu have transformed from text-prompt toys into genuine pre-visualization and B-roll engines for indie filmmakers, game developers, and social media marketers.
Silicon Valley still holds tremendous advantages in foundational research, frontier reasoning models, and enterprise distribution. Yet in the visual domain, hesitation proved costly. While American labs spent a year perfecting press releases and safety whitepapers, Chinese engineers built the infrastructure, absorbed the user feedback, and captured the daily habits of creators worldwide. In technology markets, momentum belongs to whoever puts working tools into the hands of builders first.